Jixin (Kevin) Yan

I am an undergraduate in Computer Science at Northwestern University’s McCormick School of Engineering. At Northwestern, I have worked with Prof. Qi Zhu in the IDEAS Lab and Prof. Naichen Shi in the IAI Lab. I also spent a summer at Tsinghua University with Yiming Li. My research interests are agentic robotics, embodied planning and reasoning, and foundation models for robotics.

Portrait of Jixin Yan

Research Interests

Agentic Robotics
Robot agents that coordinate planning, execution, independent verification, and failure recovery, and reuse experience across tasks.
Embodied Planning and Reasoning
Long-horizon manipulation and navigation through grounded reasoning, task decomposition, and simulation-based evaluation of candidate plans.
Foundation Models for Robotics
Vision-language-action models and world models that connect perception, reasoning, and control for general-purpose robots.

News

Earlier news 5
  • Awarded the Northwestern Summer Undergraduate Research Grant.

  • Awarded the Northwestern Academic Year Research Grant.

  • Started research at the IDEAS Lab, contributing to SENTINEL and ManiGuard, which benchmark foundation-model-based policies on safety awareness via formal verification.

  • Started research with Prof. Naichen Shi on generative Bayesian filtering for laser powder-bed fusion monitoring.

  • Started B.S. in Computer Science at Northwestern University.

Publications

RoboDoctor: Training-Free Recursive Self-Improvement for Robot Policies

Heyang Yu, Haomin Li, Sihang Li, Jixin Yan, Shiyun Peng, Wanqi Zhong, Tianyu Xin, Yuan Yao, Xiaoyu Tian, Yiming Li

arXiv preprint2026

A training-free system that improves a frozen world-action model at every decision and across episodes, through an observe–diagnose–treat loop and a shared experience memory.

Details

A training-free recursive self-improvement system for robot policies that improves behavior at each decision and across episodes without retraining. Each decision follows an observe–diagnose–treat loop: an agent inspects the scene, verifies a grounded correction to an action chunk while the world-action model (WAM) stays fixed, and execution feedback is stored in experience memory for reuse.
MANIGUARD: A Benchmark and Data Suite for Specification-Grounded Safety Evaluation and Improvement of Robotic Manipulation

Yiyan Peng, Philip Wang, Simon Sinong Zhan, Yiqi Lyu, Zhenyang Ni, Jixin Yan, Fiorelli Wong, Ruochen Jiao, Hang Yin, Xinyu Cao, Huajie Shao, Manling Li, Ruohan Zhang, Qi Zhu

arXiv preprint2026

A benchmark and data suite with 1,000 evaluation scenarios and 8,000 safety-annotated demonstrations that scores task success and safety separately, in simulation and on a real Franka arm.

Details

A specification-grounded benchmark and data suite for robotic manipulation, with six task families, 200 base tasks, 1,000 evaluation scenarios, and 8,000 safety-annotated demonstrations. Runtime safety monitors evaluate task completion and safety independently in simulation and on a physical Franka platform.

Generative Bayesian Filtering for State Estimation

Lei Cao, Sihang Feng, Jixin Yan, Tao Sun, Naichen Shi

arXiv preprint2026

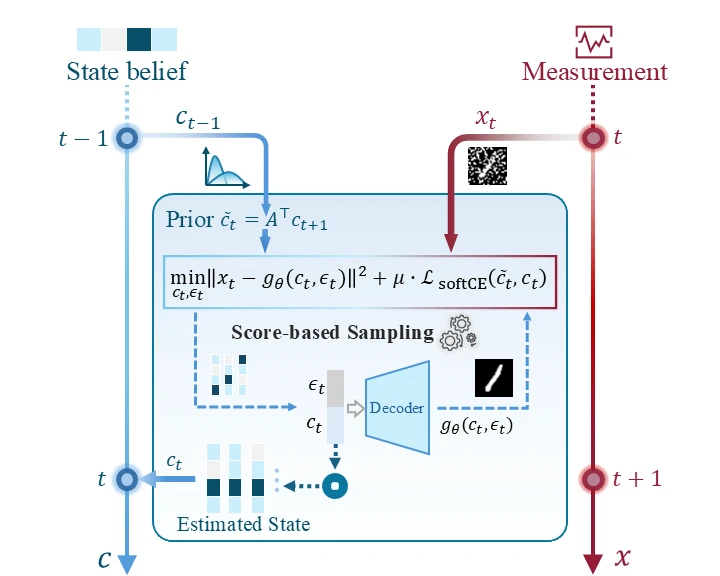
An online generative Bayesian filtering algorithm for manufacturing state estimation that uses conditional VAEs as learned likelihoods, demonstrated on laser powder-bed fusion defect monitoring.

Projects

Embodied DeepSeek Harness

Litchi AI @ Tsinghua Spatial Intelligence LabJun 2026 – Present

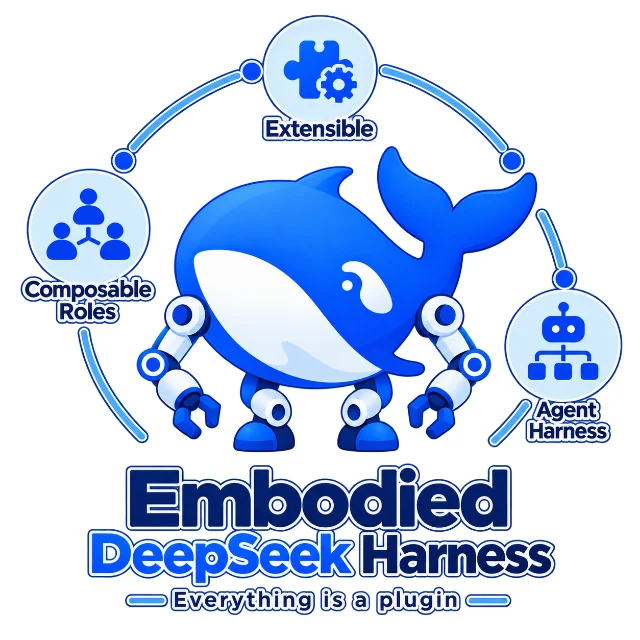
A multi-agent robot framework in which a Planner executes and retries, a Verifier checks outcomes independently, and an Evolver turns experience into reusable skills.

Details

Independently built a composable embodied multi-agent framework on DeepSeek Harness for planning, execution, verification, and recovery. Planner owns execution and retries, Verifier independently assesses outcomes, and Evolver extracts experience for RSI workflows.

Environment adapters integrate VLA, Code-as-Policies, and GPT-as-Policy; ActionGate checks parameters, observation freshness, ownership, and action budgets. Source-linked SKILL retrieval, on-demand section reading, and context compaction support experience reuse. A native RoboDojo/Pi0.5 retained-scene retry passed independent verification, with 61 controls audited against simulator receipts. Project benchmarks: VLN-CE success rate +10 percentage points over InternVLN and SOTA success rates on multiple RoboDojo tasks.

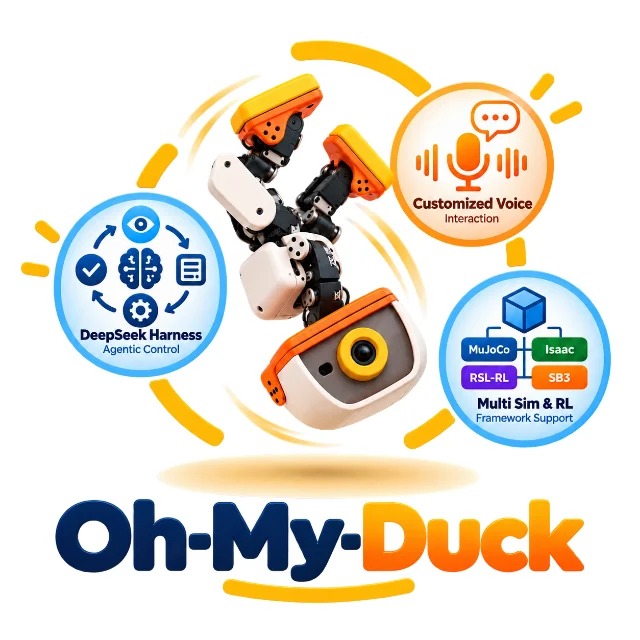
Oh My Duck: Microduck Learning and Interaction

Personal projectAug 2026 – Present

Simulation, RL training, and voice interaction for the Microduck robot: policies trained in MuJoCo-Warp and Isaac Lab walk and turn to measured targets on spoken commands.

Details

Independently built a Microduck simulation, training, and interaction framework integrating MuJoCo-Warp, Isaac Lab with Newton physics, RSL-RL/SB3 PPO, and normalized policy export. Sensor and motion tools connect an external agent harness to official pretrained policies, with measured-distance walking, measured-angle turning, braking, and stop confirmation.

Qwen3-ASR/TTS provides persistent voice profiles, native task submission, and cancellation; spoken-instruction simulation tasks and real microphone/speaker interruption have been verified. All 15 motion cases passed across apartment, Office, and Hospital simulations: position error ≤5 cm, angle error ≤5°, upright stopping, and zero external-obstacle contacts, checked by an independent artifact verifier.

OpenSO-101: End-to-End Robot Learning Framework

Personal projectApr 2026 – Present

One pipeline for the SO-101 arm from teleoperated data collection to simulation training and real deployment; ACT and Diffusion policies run on the physical arm.

Details

Independently built an SO-101 learning framework unifying teleoperation, dual-camera datasets, Isaac Lab PPO/distillation, LeRobot ACT/Diffusion training, and deployment. ACT and Diffusion policies were demonstrated on a physical SO-101.

Asynchronous arm polling, synchronized HDF5 recording, LeRobot export, and simulator replay provide a reproducible data workflow; all 2,281 recorded frames were checked through dataset loading and replay. An Agent-driven RGB-video scene-generation prototype uses Objaverse retrieval, scene composition, and physics/readiness review. A scene generated from simulation video passed runtime checks across four Isaac environments, 100 resets, and 200 control steps.

Experience

  1. Northwestern University

    B.S. in Computer Science, McCormick School of Engineering

    Sep 2025 – Jun 2028 (expected)

    1. IDEAS Lab

      Research Assistant

      Advisor: Prof. Qi Zhu

      Jan 2026 – Jun 2026

    2. Integrative AI (IAI) Lab

      Research Assistant

      Advisor: Prof. Naichen Shi

      Jan 2026 – Sep 2026

  2. Jun 2026 – Present

Selected Honors